Synametrics Technologies
Revolving around the core of technology
Connecting to Amazon Redshift with JDBC
Benefits
Using a JDBC connection to Amazon Redshift will greatly enhance your ability to work with the database. By doing this, you add a multitude of features, but most importantly, you make querying the database a much easier task. Additionally, you can use several third-party reporting and querying tools that aren't otherwise available.
In this article, we are going to cover how to connect to Amazon Redshift through JDBC. This article uses SyncriTab, a powerful SQL query tool with additional features.
Connecting to Redshift
First, you will need to enable outside connections to your Redshift instance so that SyncriTab can connect.
Step 1: Enable Public Accessibility
To do this, go to your AWS management console. Go to Amazon Redshift, and click PROPERTIES.
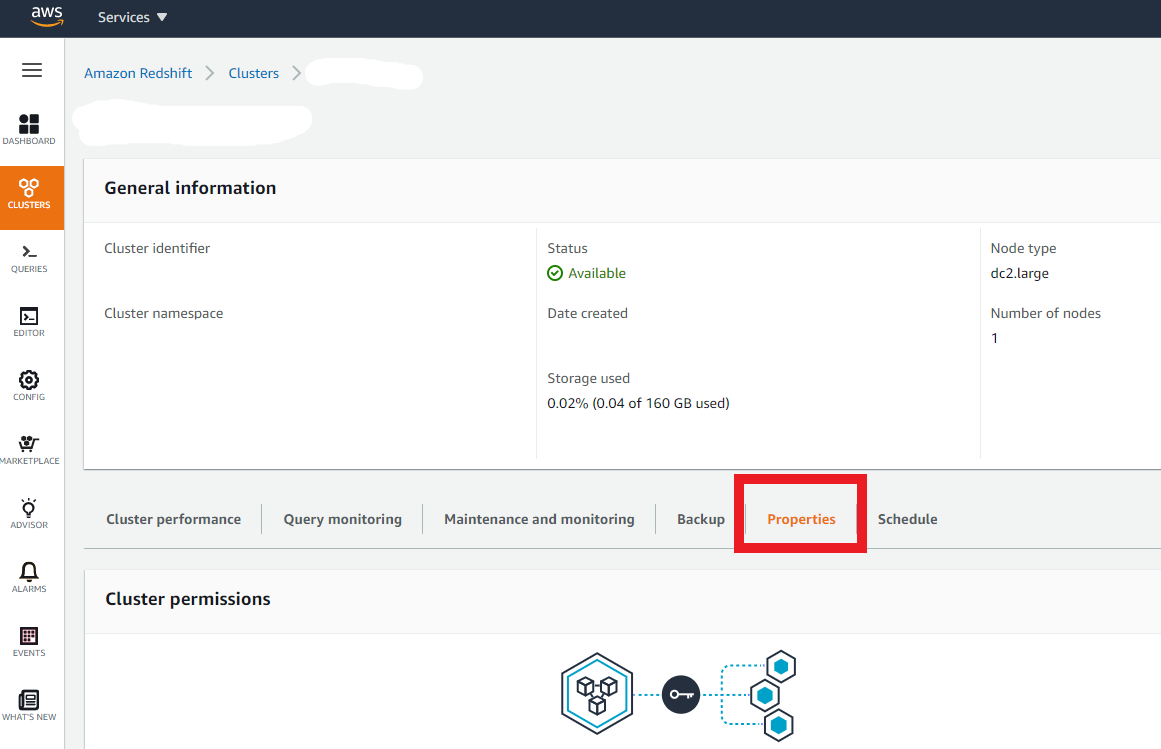
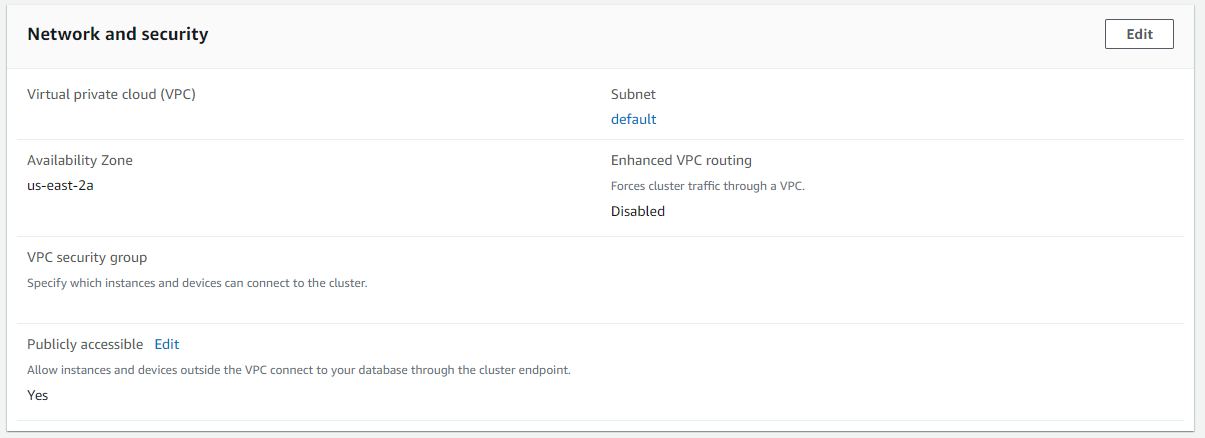
On the Properties tab, scroll down to the Network and Security section and edit the Publicly Accessible status to Yes.
Step 2: Obtain your JDBC Connection String
The easiest way is to copy your endpoint into Notepad. Your endpoint will be under "General Information" at the top of your "Properties" page that you are on from Step 1 above.
The endpoint will provide you with something similar to the following:
YourCluster.us-east-2.redshift.amazonaws.com:####/dbName
Note: YourCluster will be the name of your cluster. The port is the port your Redshift cluster listens on, and dbName is the name of the Database you connect to.
Additional Note: If you are using Redshift Serverless instead, this value will be shown in your Workgroup configuration.
Configuring JDBC Connection to Redshift and Running Queries
The following section explains how to configure the Redshift connection to download the JDBC drivers and run queries in SyncriTab. Select the other tab if you need instructions for WinSQL
Step 3: Configure the Connection in SyncriTab
- Open SyncriTab and log in as an administrator or DB manager.
- Click on Manage Data Sources on the left side.
- Click "Add Data Source".
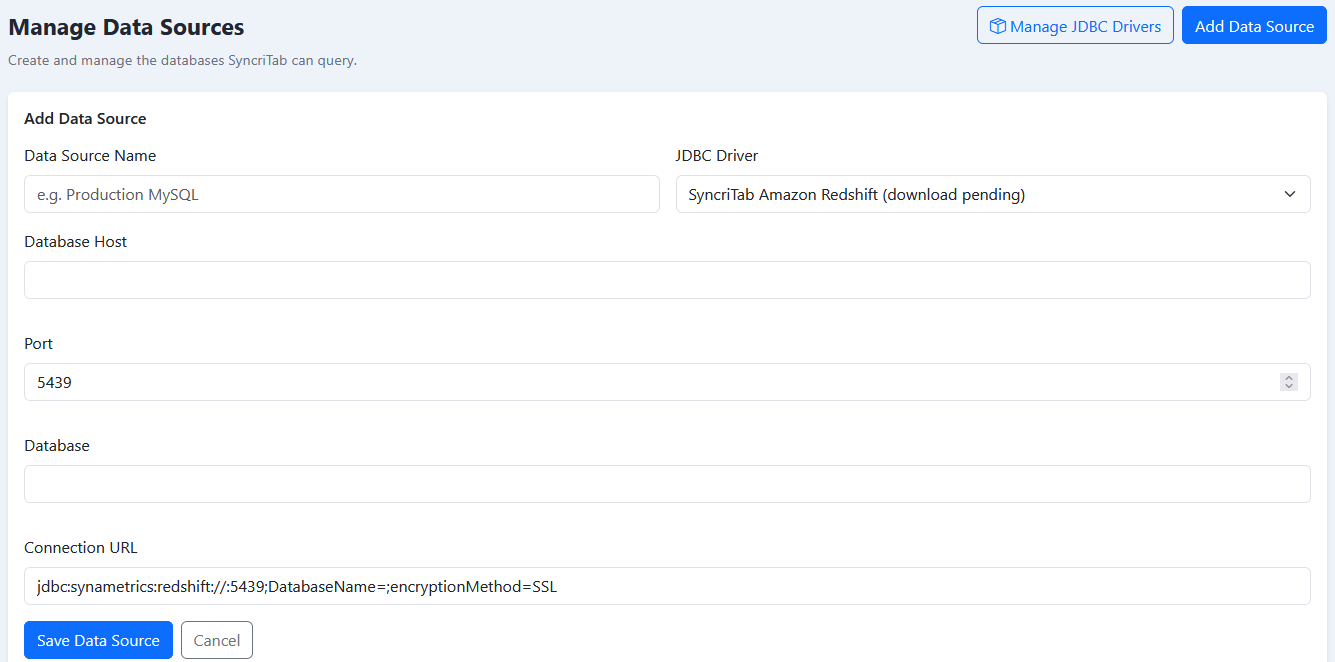
- In the JDBC Driver field, select SyncriTab Amazon Redshift
You will need to fill out the following fields:
| Field | Description |
|---|---|
| Data Source Name | This is a friendly name you want to apply to this Data Source. |
| Database Host | This is copied directly from your endpoint. Copy everything up to the port number: YourCluster.us-east-2.redshift.amazonaws.com |
| Port | By default, the port is 5439. To confirm this, look at the number directly after the hostname value. For example, YourCluster.us-east-2.redshift.amazonaws.com:5439 |
| Database | Database: This is also copied directly from your endpoint and follows the port number, and is typically the last thing in the endpoint string. YourCluster.us-east-2.redshift.amazonaws.com:####/dbName |
| Connection URL | Connection URL: You do not need to modify this value. Once you specify the values above, this field will automatically be adjusted. |
After specifying the values, click on Save Data Source. SyncriTab will automatically download the Redshift JDBC drivers. Next, configure authentication. You can authenticate to your Redshift database in several ways, including Standard Auth, AWS Profiles, and AWS IAM Credentials. It is up to your database administrator to determine which set of credentials is necessary for you.
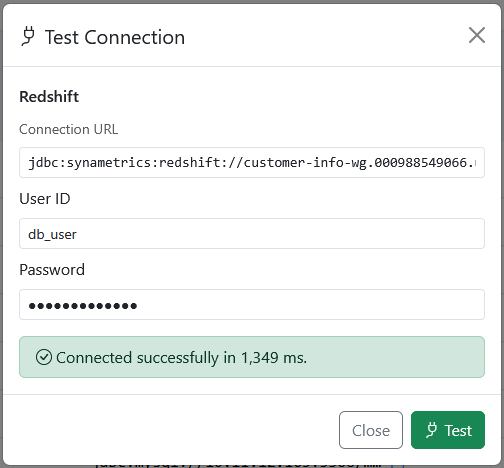
After you create the data source, you should see it as an existing Data Source. For this Data Source, click the "Test" button. If there are no issues, you should see a "Connected Successfully" message:
Step 4: Manage Access to Redshift in SyncriTab
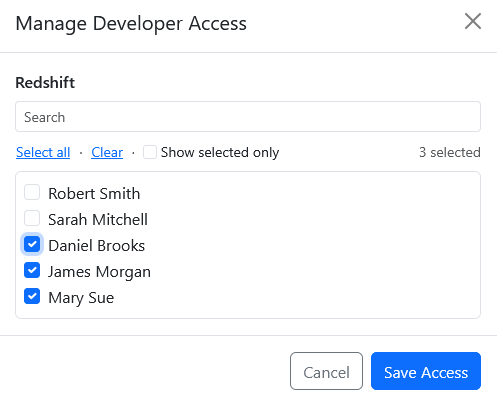
Once you add the data source and can connect, add users who need access to Redshift. Follow the instructions below to do this:
- Open SyncriTab and log in as an administrator or DB manager.
- Click on Manage Data Sources on the left side.
- Look for the Redshift Data Source. Click on the Manage Access button on the right side under the Action Column.
- Select the users you want to add access for, then click on Save Access:
Step5: Running Queries and Interacting with Amazon Redshift
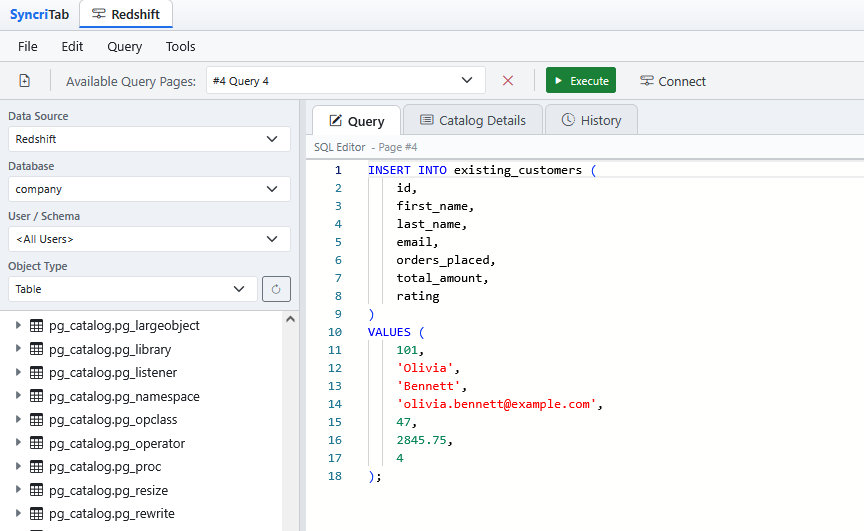
Now that we are successfully connected, we can begin running queries and modifying the database.
In this example, I am adding a new customer to my customer database:
If I browse the data, I can see the new user:
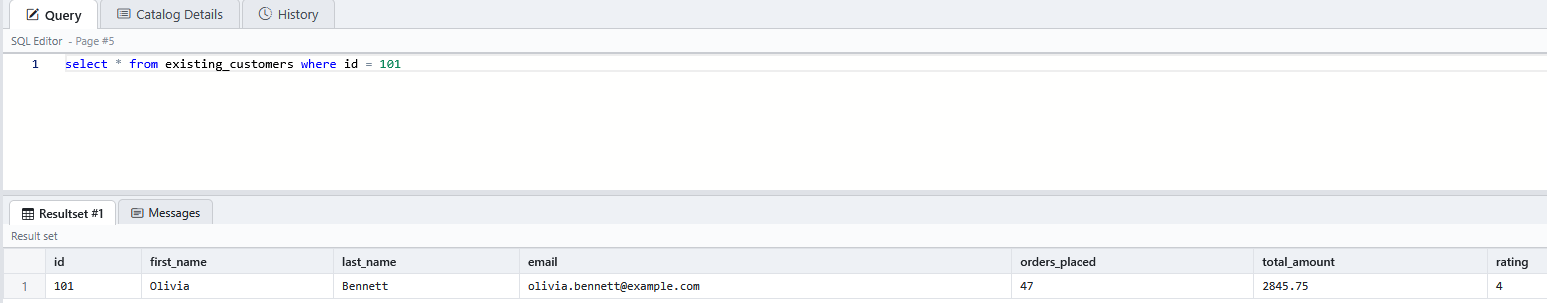
Using your JDBC query tool, you can interact with Redshift as if you were using the Query Editor directly. The benefit is that you also get the full suite of your chosen tool, plus a much more informative interface.
Step 3: Configure the Connection in WinSQL
- Open WinSQL and click on File, then click on New Connection...
- Click on JDBC Manager on the right side.
- Click Add under User DSN.
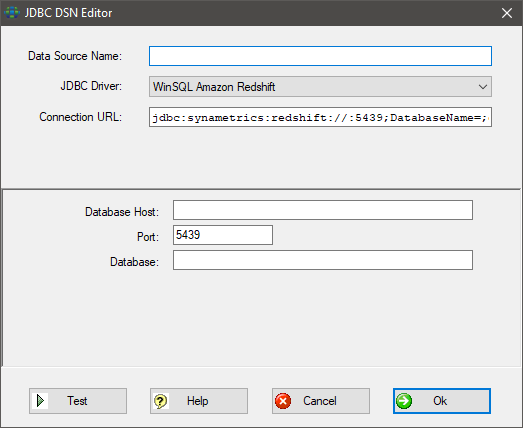
- In the JDBC Driver field, select WinSQL Amazon Redshift
You will need to fill out the following fields:
| Field | Description |
|---|---|
| Connection URL | Connection URL: You do not need to modify this value. Once you specify the values below, this field will automatically be adjusted. |
| Data Source Name | This is a friendly name you want to apply to this Data Source. |
| Database Host | This is copied directly from your endpoint. Copy everything up to the port number: YourCluster.us-east-2.redshift.amazonaws.com |
| Port | By default, the port is 5439. To confirm this, look at the number directly after the hostname value. For example, YourCluster.us-east-2.redshift.amazonaws.com:5439 |
| Database | Database: This is also copied directly from your endpoint and follows the port number, and is typically the last thing in the endpoint string. YourCluster.us-east-2.redshift.amazonaws.com:####/dbName |
After specifying the values, click on Save Data Source. SyncriTab will automatically download the Redshift JDBC drivers. Next, configure authentication. You can authenticate to your Redshift database in several ways, including Standard Auth, AWS Profiles, and AWS IAM Credentials. It is up to your database administrator to determine which set of credentials is necessary for you.
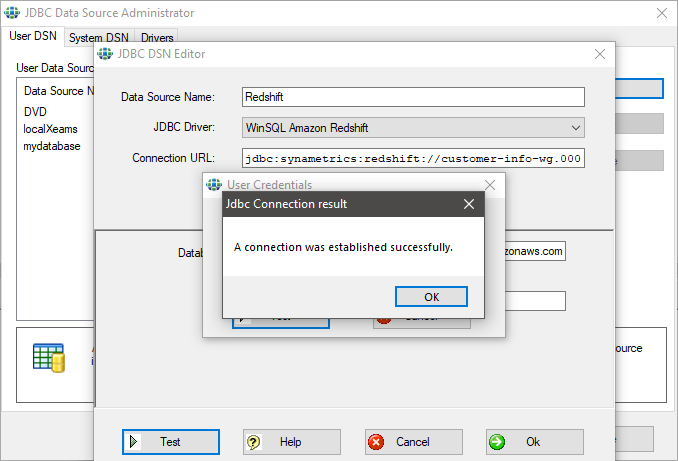
After you specify the values, click the "Test" button. Enter a username and password that can access Redshift, then click on Test. WinSQL will download the necessary JDBC drivers. If the connection is successful, then you will see "A connection was established successfully" prompt:
Step 4: Connecting to Redshift in WinSQL
Once the connection test is successful, click Ok, and you should now see this in the UserDSN list. Click Close.
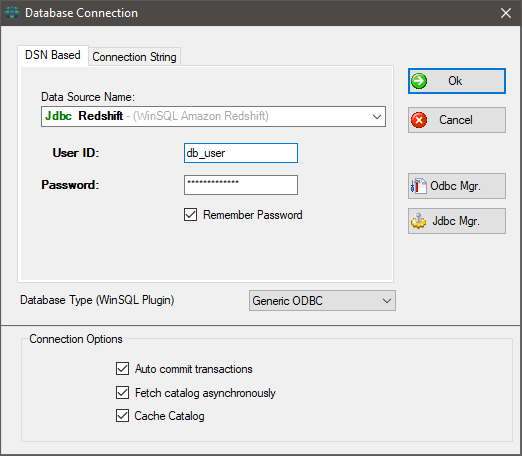
You should now see the Database Connection prompt. In the Data Source Name field, select the JDBC Redshift you created in the previous step. Specify the correct username and password, then click on Ok:
Step5: Running Queries and Interacting with Amazon Redshift
Now that we are successfully connected, we can begin running queries and modifying the database.
In this example, I am adding a new customer to my customer database:
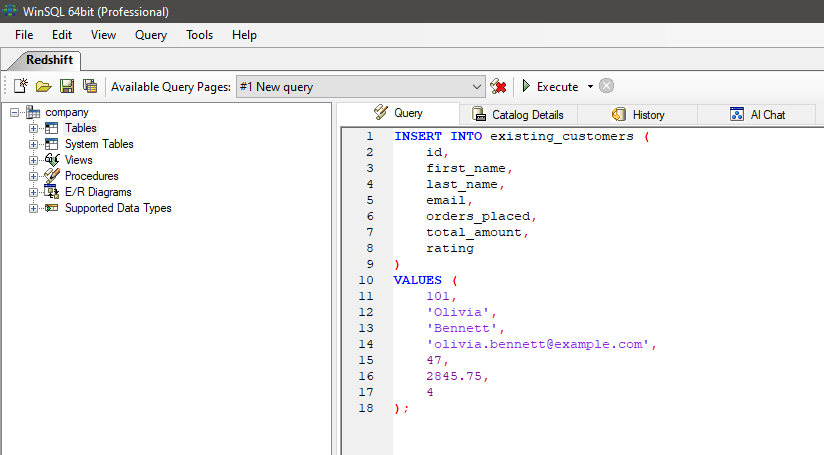
If I browse the data, I can see the new user:
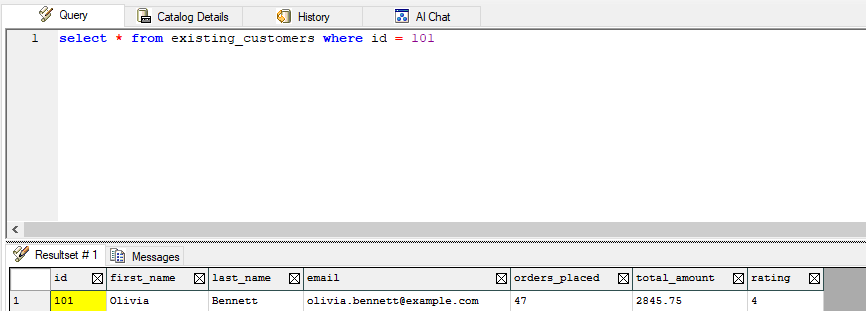
Using your JDBC query tool, you can interact with Redshift as if you were using the Query Editor directly. The benefit is that you also get the full suite of your chosen tool, plus a much more informative interface.